Modernizing high-risk systems in the age of AI.
The Little Engine that Could
On September 30, every domain on Railway started returning 404s. It lasted five minutes. The routing service came up while the schema migration was still running. Nothing in the pipeline required the migration to finish first.
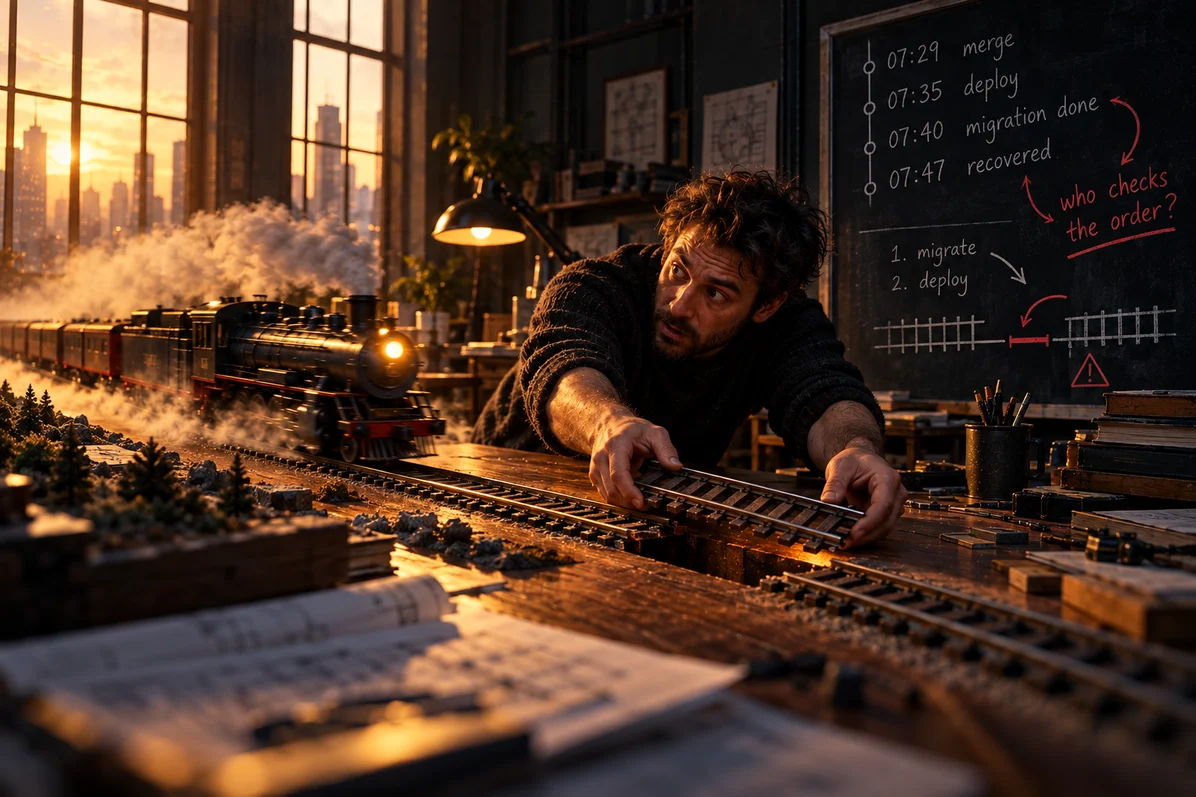
On the morning of September 30, every domain hosted on Railway started returning 404s. Custom domains, *.up.railway.app, private networking lookups between services, all of it, in every region, for new connections. It lasted five minutes.
Here's the timeline: 07:29, an engineer merged a change to the routing control plane that included a database schema update. 07:35, the deployment system rolled out the new routing service while the schema migration was still running alongside it. The service came up, queried columns that did not exist yet, and failed every route lookup it attempted. 07:40, the migration finished and routing recovered on its own. 07:44, root cause is determined. 07:47, full recovery confirmed. 07:48, public incident posted.
Existing connections stayed up. Workloads kept running. No data was lost. The problem was that nothing in Railway's pipeline required the migration to finish before the service that needed it started.
The Pipeline Didn't Enforce the Order
Railway's routing service depended on a schema that had to exist before it started. For most of the history of deploying software, that ordering held without anyone enforcing it, because deployments were slow and serial and a human was usually watching one step finish before starting the next. This was a beneficial side effect of the pipeline being slower than the thing it was deploying.
"Speed kills," as they say. Now that the pipeline is fast enough to run both steps at once, that beneficial side effect is swept away and a production outage ensued.
The failure deserves attention as it is the one this newsletter keeps coming back to. Implementation got faster than the thing that used to verify it, and nobody noticed because the verification was not codified anywhere.
Prevention vs. Containment
Railway came out of this well, and some of that was design and some of it was luck. The migration finished on its own, so routing recovered without anyone touching it. Existing connections were unaffected. Running workloads never noticed. No data was lost. Change any one of those and the same mistake is a different morning. A migration that fails rather than running slowly leaves the routing service querying columns that are never going to exist, and five minutes becomes however long it takes someone to work out what happened.
The fixes Railway named are across two categories. The first is preventative: ordering enforcement and schema gates exist to keep the mistake from happening. However, shard-based rollouts assume it will happen anyway and keep it to one region. That's the interesting one for me, because it's a perfect example of Governance as Containment. The first GUIDE principle is Governance, and when we employ it with our clients we focus on containment. Many teams stop at prevention, which is laudable in its own right but does not go far enough in an AI world. We know enough now to understand that things will go wrong for reasons we can't easily predict or explain. However true this may have been in the past, AI has been an accelerant of the axiom.
Kudos to Railway for assuming that their preventative measures would one day fail them and employing a containment strategy. What strategies are you employing at your organization? If your deployment velocity doubled tomorrow, would your failures stay the same size? Railway's velocity doubled the moment the pipeline could run two steps at once, and the failure reached every region. So go look for the requirements your systems currently satisfy by accident. Deployment ordering is one. The migration that works because the old column is still there. The job that finishes on time because the queue happens to be short. Write those down as checks while they are still working. Railway's five minutes owed something to luck. The shard-based rollouts they're adding are the part that won't: the next failure of this kind reaches one region instead of every region, whether or not anyone saw it coming. That is what you are left with when the check you needed turns out to be one nobody wrote.
Need to modernize a high-stakes system?
GUIDE is Def Method's framework for preserving understanding, strengthening governance, and building evidence before implementation accelerates.
If this was useful, you might enjoy Essential Complexity — a bi-weekly letter on modernizing high-risk systems in the age of AI.